Introduction to PixelRAG
Most enterprise RAG pipelines start with a text parser that converts web pages and documents into plain text. However, this conversion step can destroy retrieval signals, leading to wrong answers. A research team from UC Berkeley, Princeton University, EPFL, and Databricks has introduced PixelRAG, a system that skips this conversion entirely.
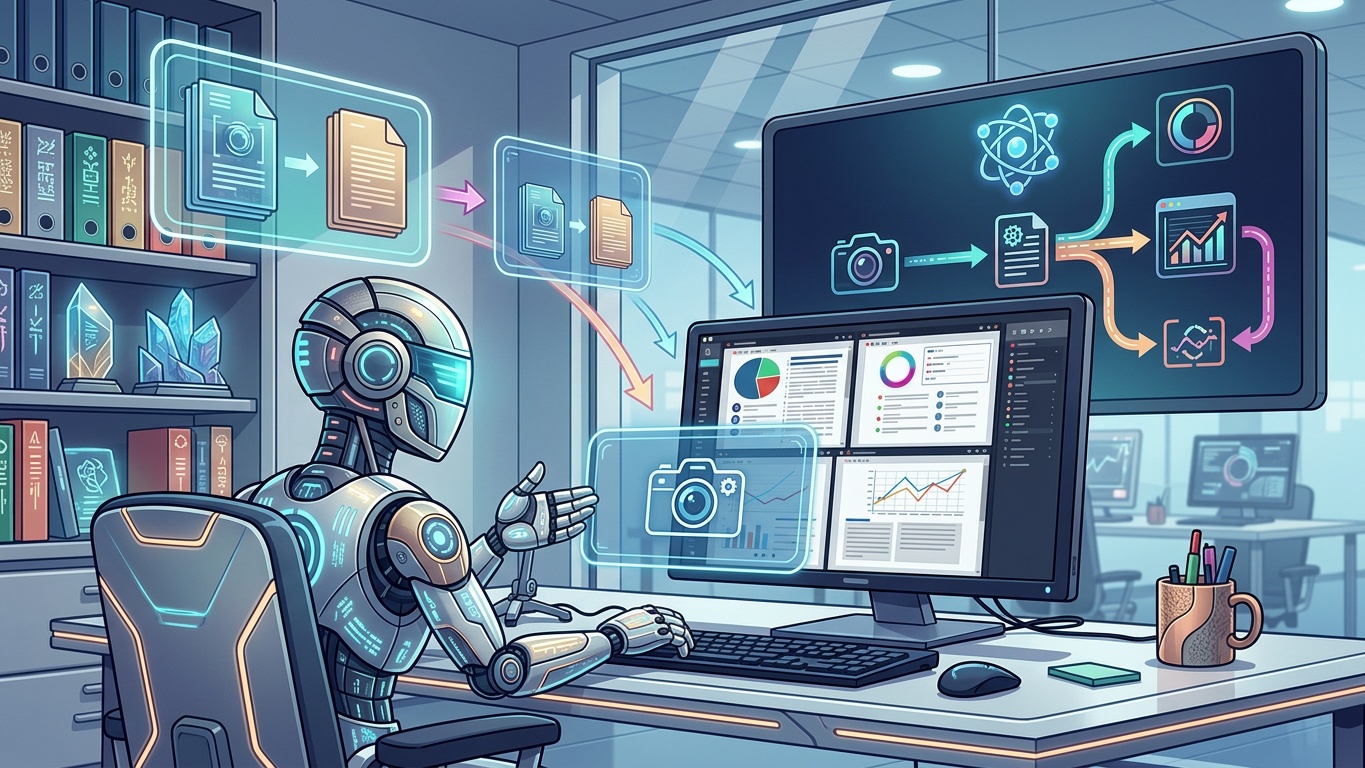
PixelRAG renders web pages as screenshots, indexes those images, and feeds retrieved tiles directly to a vision-language model reader. This approach has been tested across 30 million screenshot tiles covering all of Wikipedia, outperforming text-based RAG across six benchmarks and improving accuracy by up to 18.1% over text-based baselines.
The Problem with Text Parsers
Text parsers are often seen as the bottleneck in retrieval systems. They require special handling for every website, making it an endless process to improve them. According to Yichuan Wang, lead author and UC Berkeley doctorate student, improving parsers is not the solution.
"Our goal was to explore whether recent advances in VLMs make it possible to bypass that entire problem and build a retrieval system that doesn't rely on text parsing," Wang told VentureBeat. This approach has led to the development of PixelRAG, which has shown promising results in improving retrieval system efficiency.
How PixelRAG Works
PixelRAG's innovative approach involves rendering web pages as screenshots and indexing those images. This allows the system to bypass the text parsing step, which can destroy retrieval signals. The retrieved tiles are then fed directly to a vision-language model reader, which can understand the content of the images.
This approach has several advantages over traditional text-based RAG systems. For one, it eliminates the need for special handling for every website, making it a more efficient and scalable solution. Additionally, PixelRAG's use of vision-language models allows it to understand the content of images, which can lead to more accurate retrieval results.
Benefits of PixelRAG
PixelRAG's approach has several benefits, including improved accuracy and reduced costs. By bypassing the text parsing step, PixelRAG can reduce the number of wrong answers and improve the overall efficiency of the retrieval system.
Additionally, PixelRAG's use of vision-language models can lead to cost savings. According to the research team, PixelRAG can cut AI agent token costs by up to 10x. This is because the system doesn't require the same level of text parsing and processing as traditional RAG systems.
PixelRAG's benefits also extend to the environment. By reducing the need for text parsing and processing, PixelRAG can help reduce the carbon footprint of retrieval systems. This is because text parsing and processing require significant computational resources, which can lead to increased energy consumption and greenhouse gas emissions.
Conclusion
In conclusion, PixelRAG is a revolutionary new approach to retrieval systems that bypasses the text parsing step and uses vision-language models to understand the content of images. This approach has shown promising results in improving retrieval system efficiency and reducing costs.
As the use of AI and machine learning continues to grow, it's likely that we'll see more innovative approaches like PixelRAG. By exploring new ways to improve retrieval system efficiency, we can create more accurate and efficient systems that can help us make better decisions and improve our lives.
Attribution: This article is based on a report by VentureBeat, which can be found at https://venturebeat.com/data/pixelrag-beats-text-parsers-on-accuracy-and-cuts-ai-agent-token-costs-10x